A transparent memory sidecar for local and cloud LLMs. Your model remembers across sessions, corrects itself, forgets what stops mattering, and knows who told it what - with zero changes to your client.
One process. One SQLite file. No Docker, no vector DB, no cloud account. Runs on models as small as 1.7B.
Every number measured. Worst cases, losing categories, and known weaknesses published alongside the wins.
A proxy that impersonates your model server
Point any OpenAI-, Ollama-, or Anthropic-protocol client at port 11435 instead of your model. Engram recalls relevant memories, injects a small budgeted block, forwards the request, and streams the response back byte-for-byte. Afterward - only when your GPU is idle - it summarizes the exchange into memory.
Memory science, not just similarity search
ACT-R ACTIVATION
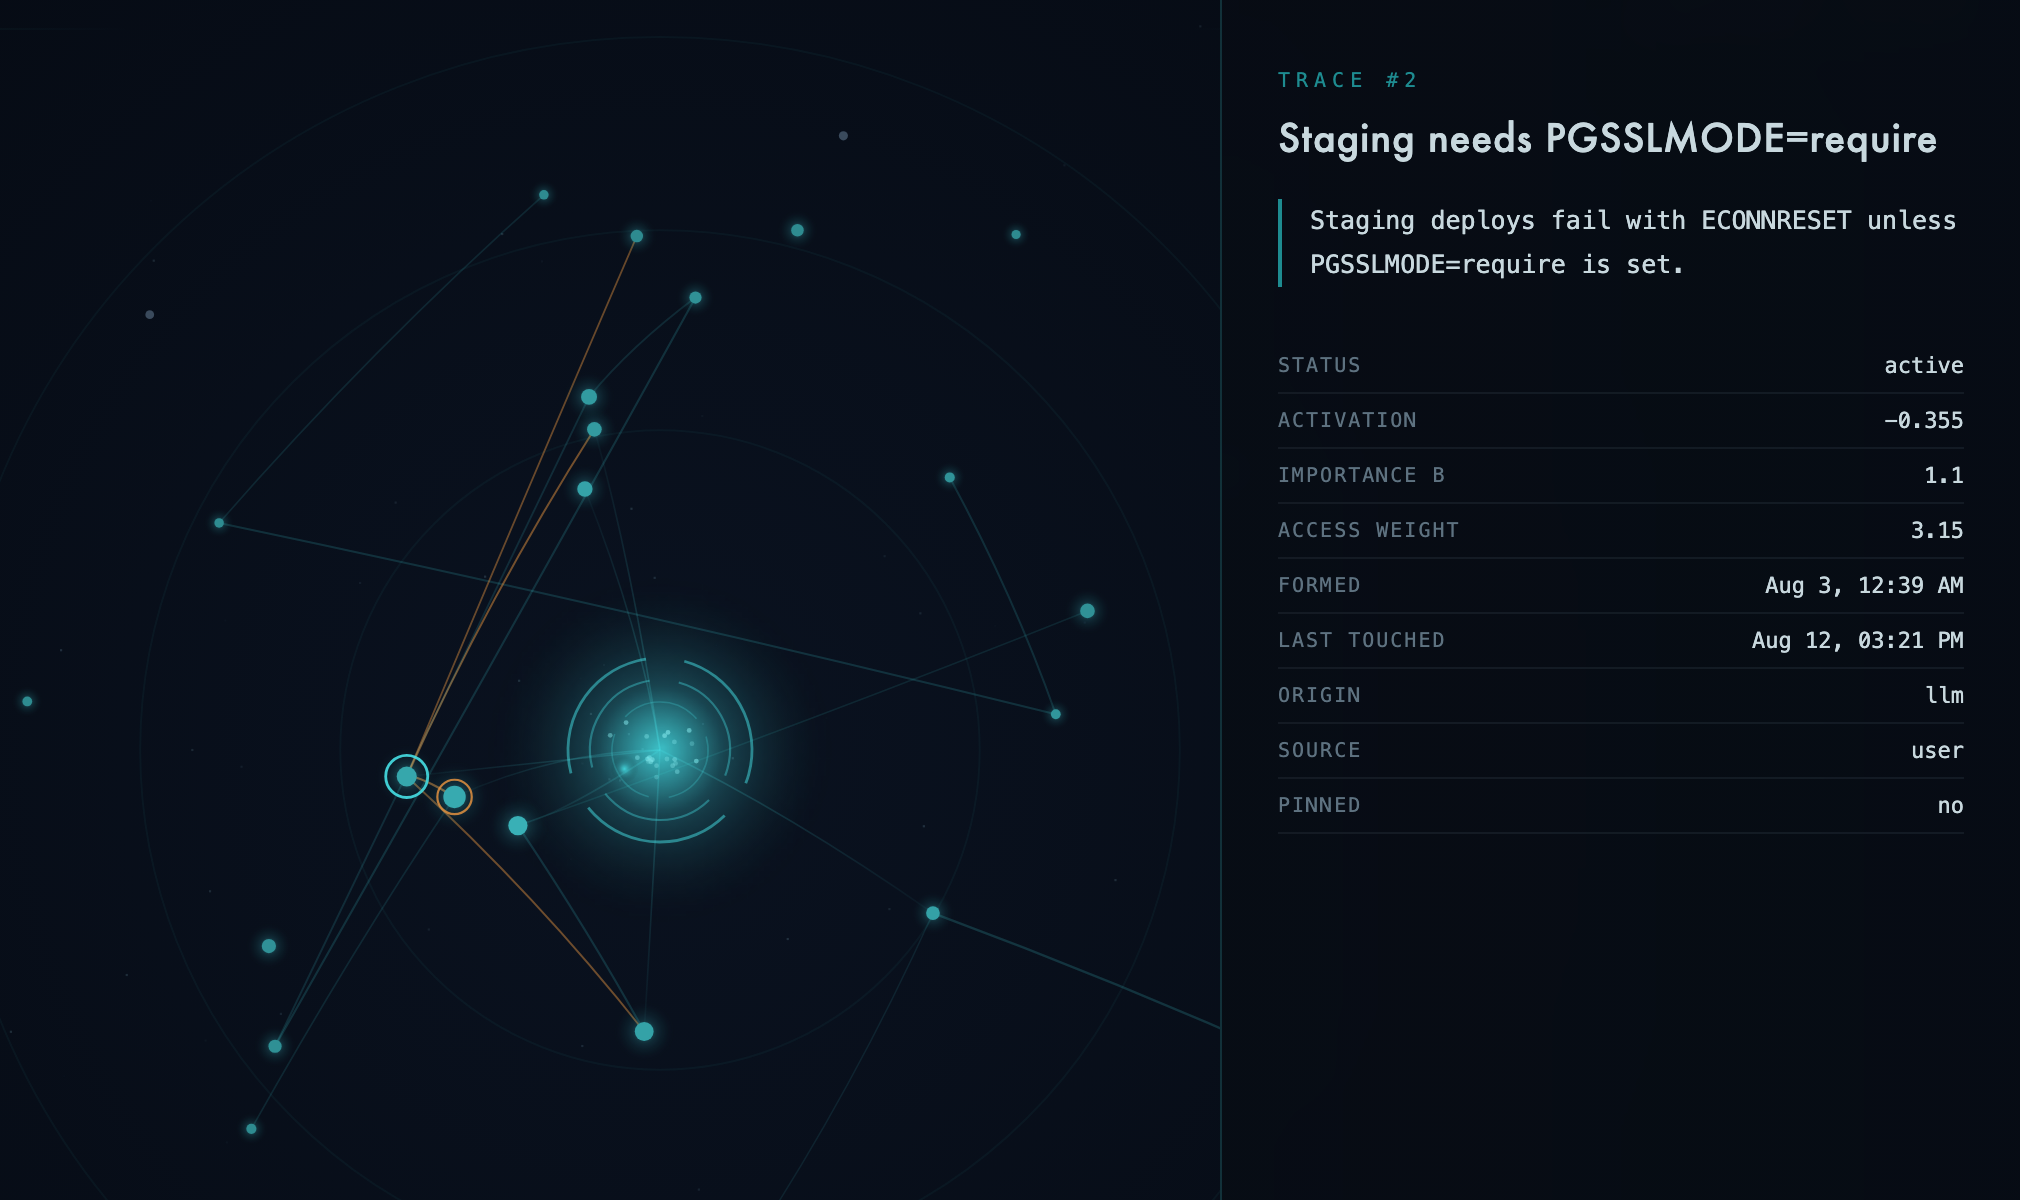
Scoring grounded in 50 years of cognitive science: B = ln(Σ w·t⁻⁰·⁵). Frequent-and-recent surfaces first; retrieval itself reinforces (the testing effect) at loop-safe weights; the rich-get-richer spiral stays closed.
PROVENANCE
Every memory knows whose words it came from: user, observed third parties, or framework plumbing. Imperatives from strangers never earn salience - that grammar is what injection attacks look like.
CORRECTIONS SUPERSEDE
"Actually it's X now" silences the stale memory instead of feeding it. History stays auditable; temporal questions stay answerable; the correction outranks.
MEMORY GRAPH
Traces wire together - temporally, semantically, and by co-retrieval (Hebbian). Recalling one primes its neighbors next turn, with fan damping so hubs can't dominate.
CLOUD, CHEAPLY
Route Anthropic- or OpenAI-protocol traffic to any compatible cloud endpoint (MiniMax, OpenRouter, DeepSeek) while embeddings and summarization stay on local Ollama. Added cloud cost: the injected block only - and cache-friendly placement keeps the provider's 5× cache-read discount.
AGENT VERBS (MCP)
Eight memory tools for agents that can call them: search (with history), save, correct, edit, pin, forget, profile, stats. Same store as the transparent proxy - ambient and explicit memory stay in sync.
THE OBSERVATORY
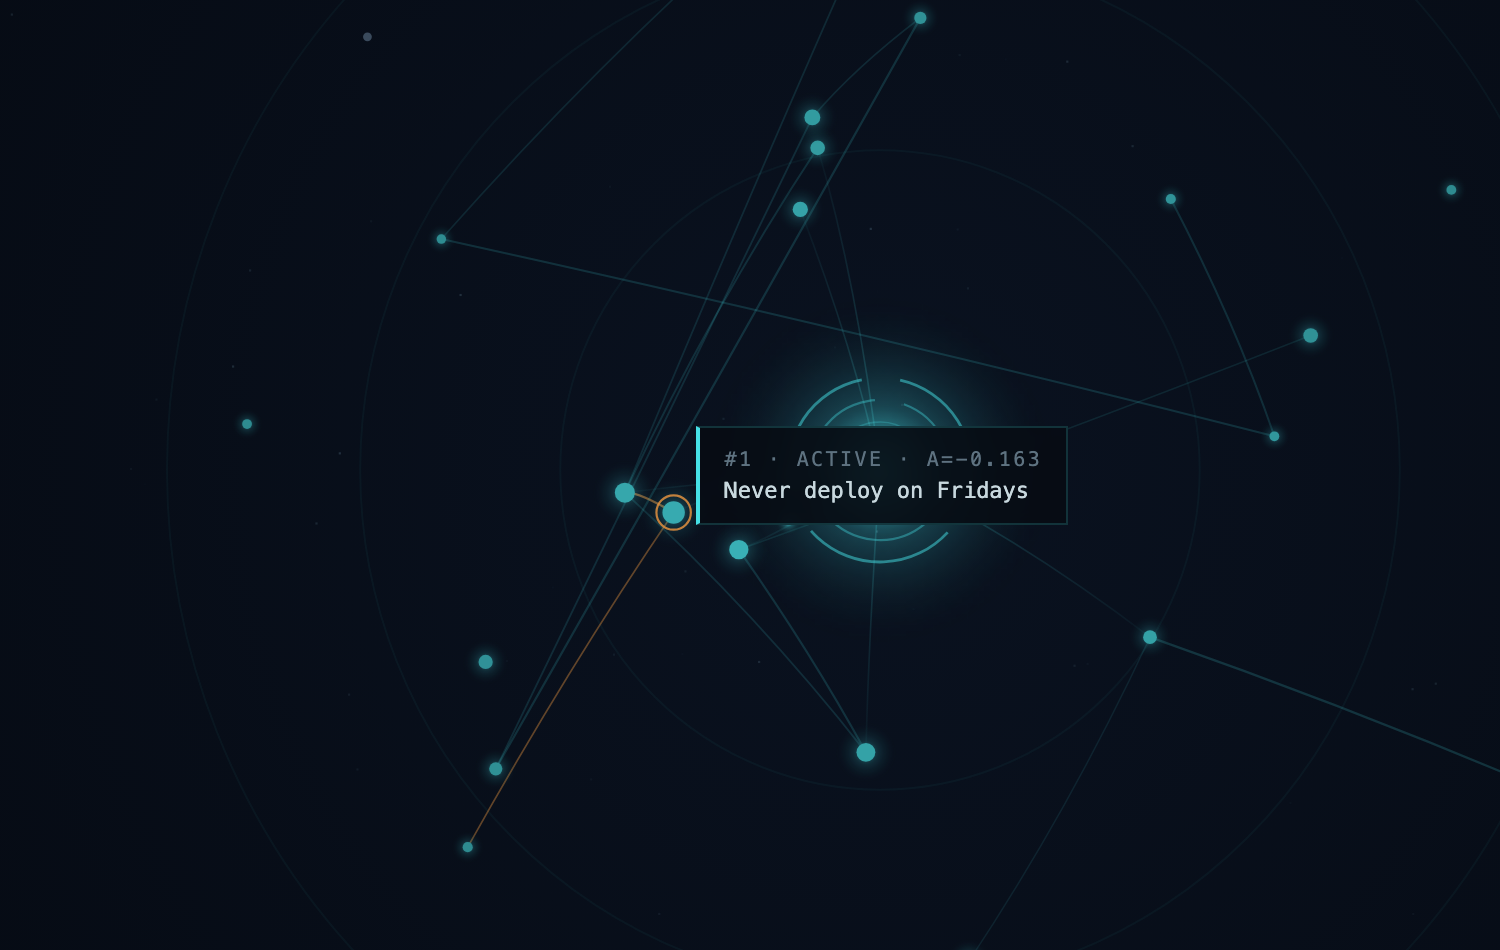
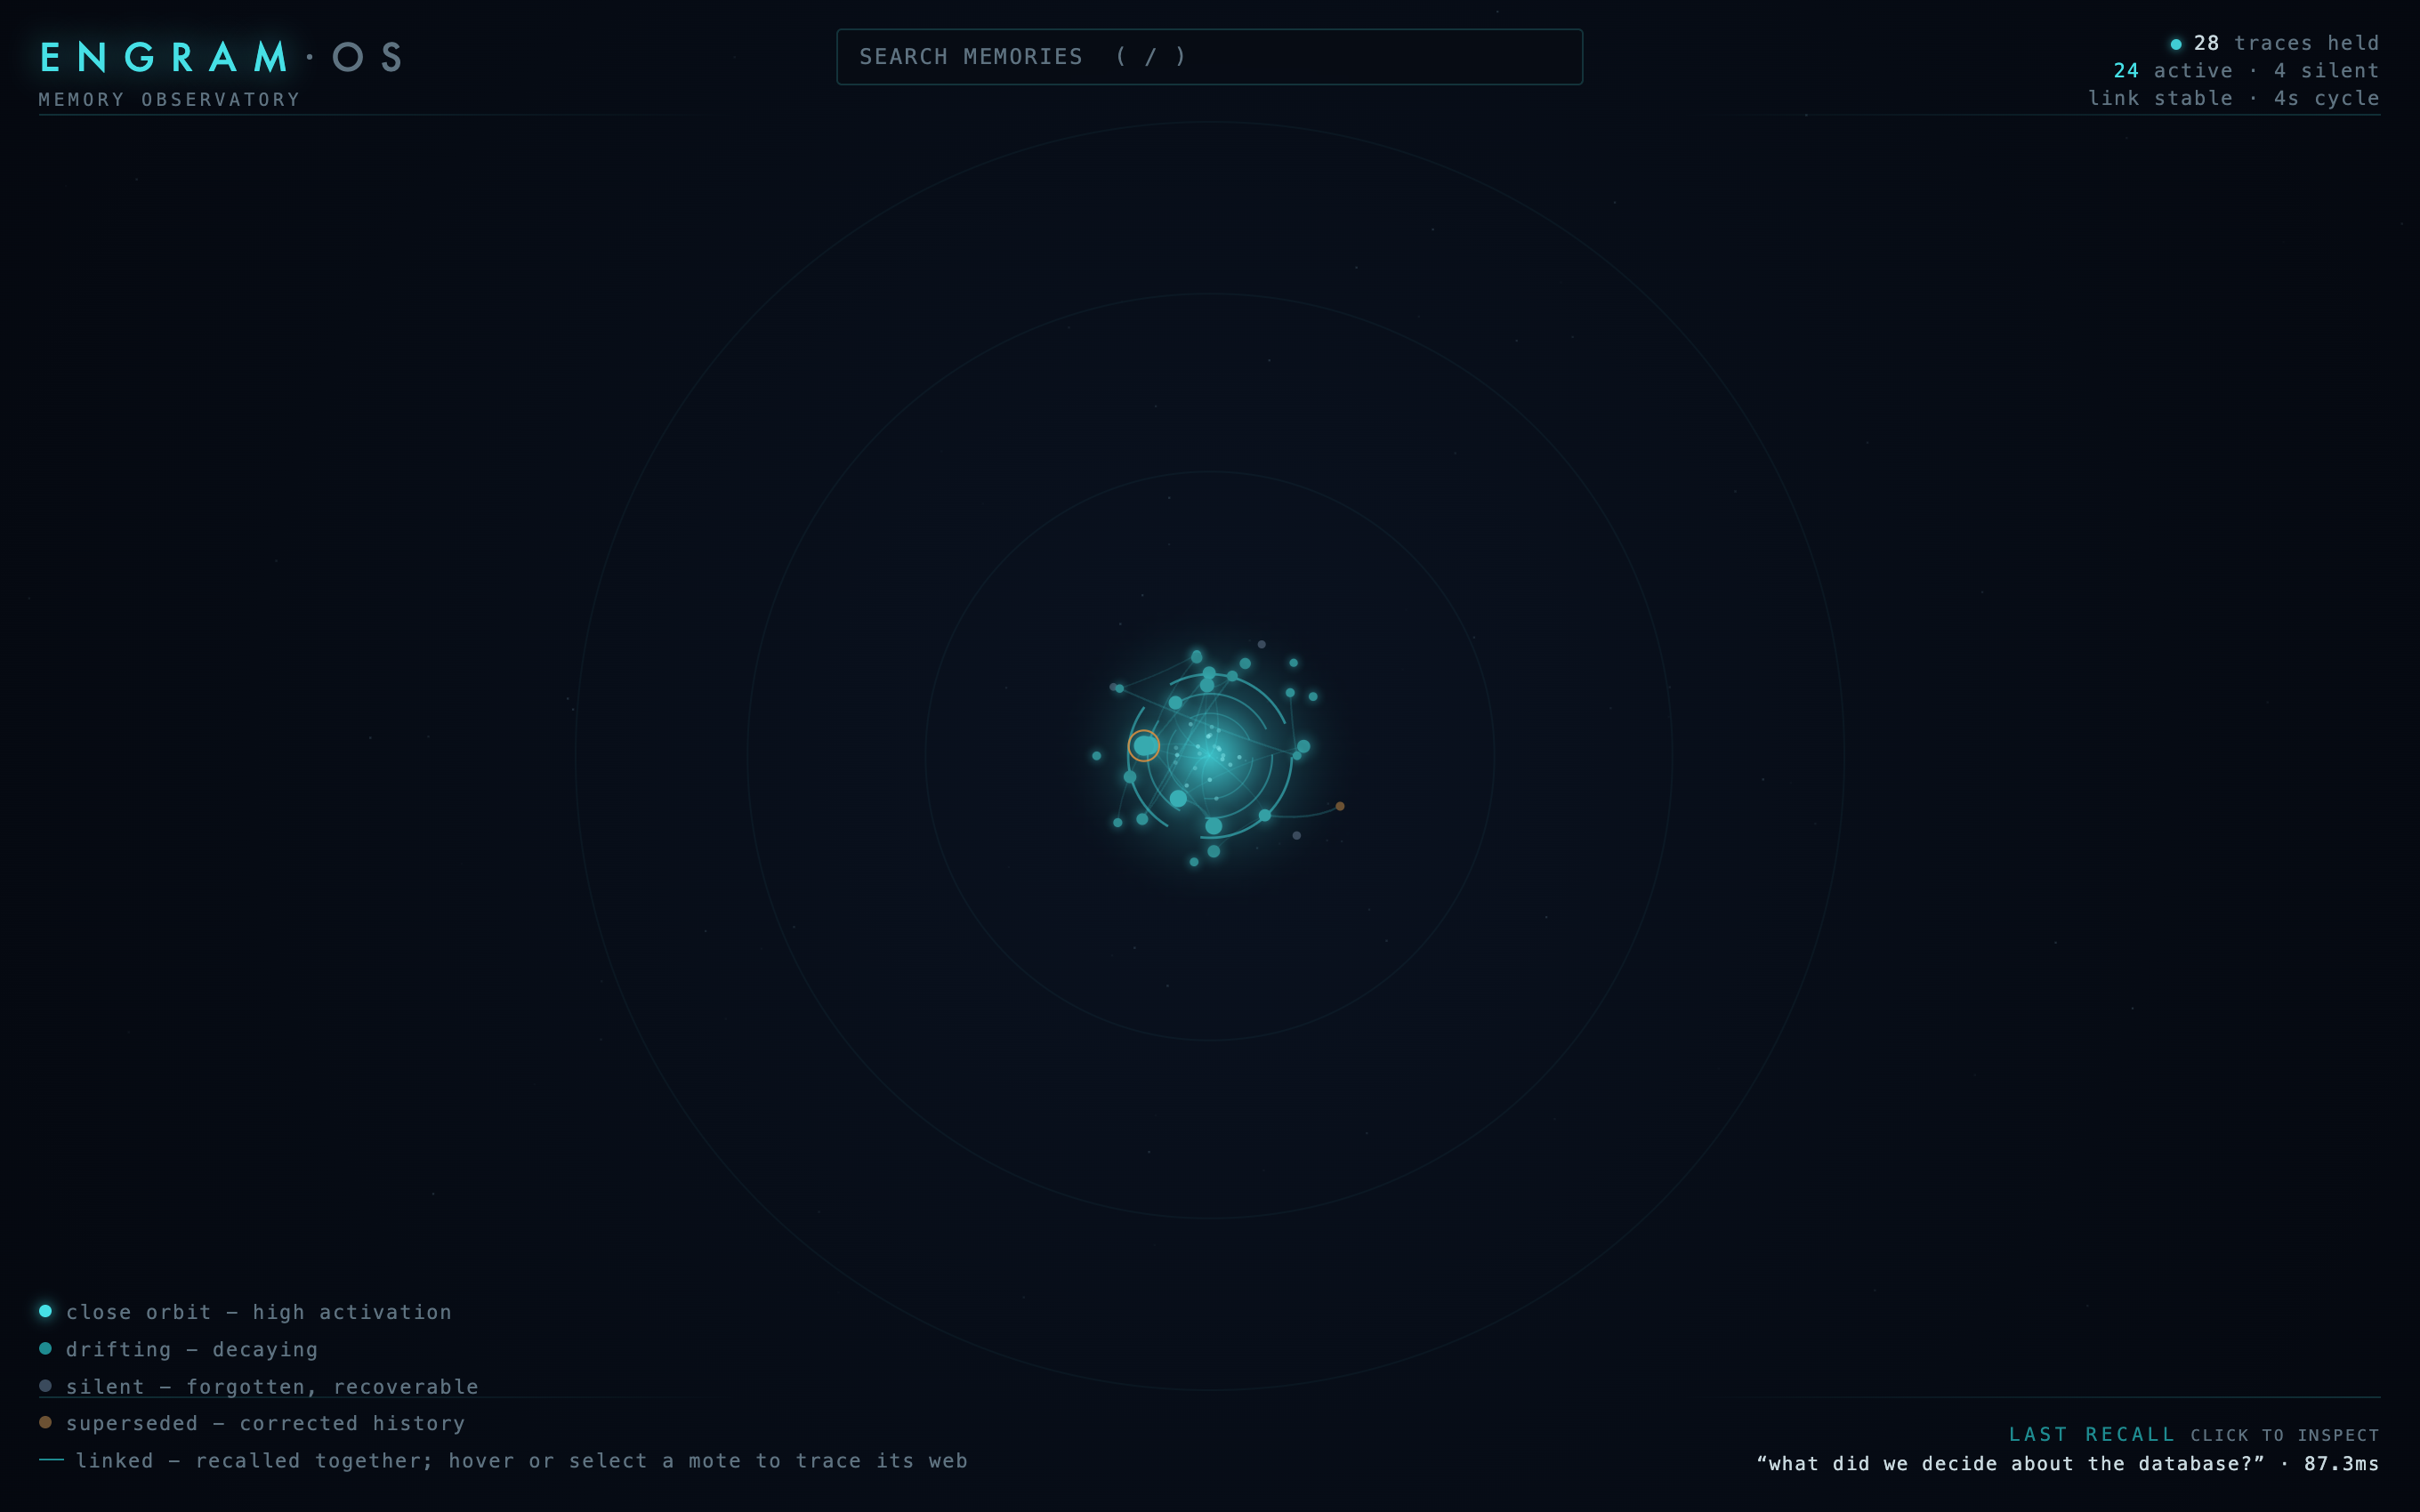
A live brain view at /engram/ui: memories orbit by activation, fall inward when reinforced, drift out as they decay, flare on recall. Search with /. Memory you can watch.
FAILS OPEN
Hard recall deadline; any failure forwards your request untouched. Byte-verbatim streaming, WAL crash safety, extractive fallbacks. Memory is an enhancement, never a gate.
Memory you can watch
Every Engram daemon serves a live brain view at /engram/ui. Memories orbit a neural core at a radius set by their live ACT-R activation: reinforced memories fall inward, decaying ones drift toward the rim, recalls flare, pinned traces wear an ember ring, corrected history dims at the edge, and the memory graph itself is drawn: faint filaments between memories that are recalled together. Press / to search the constellation.
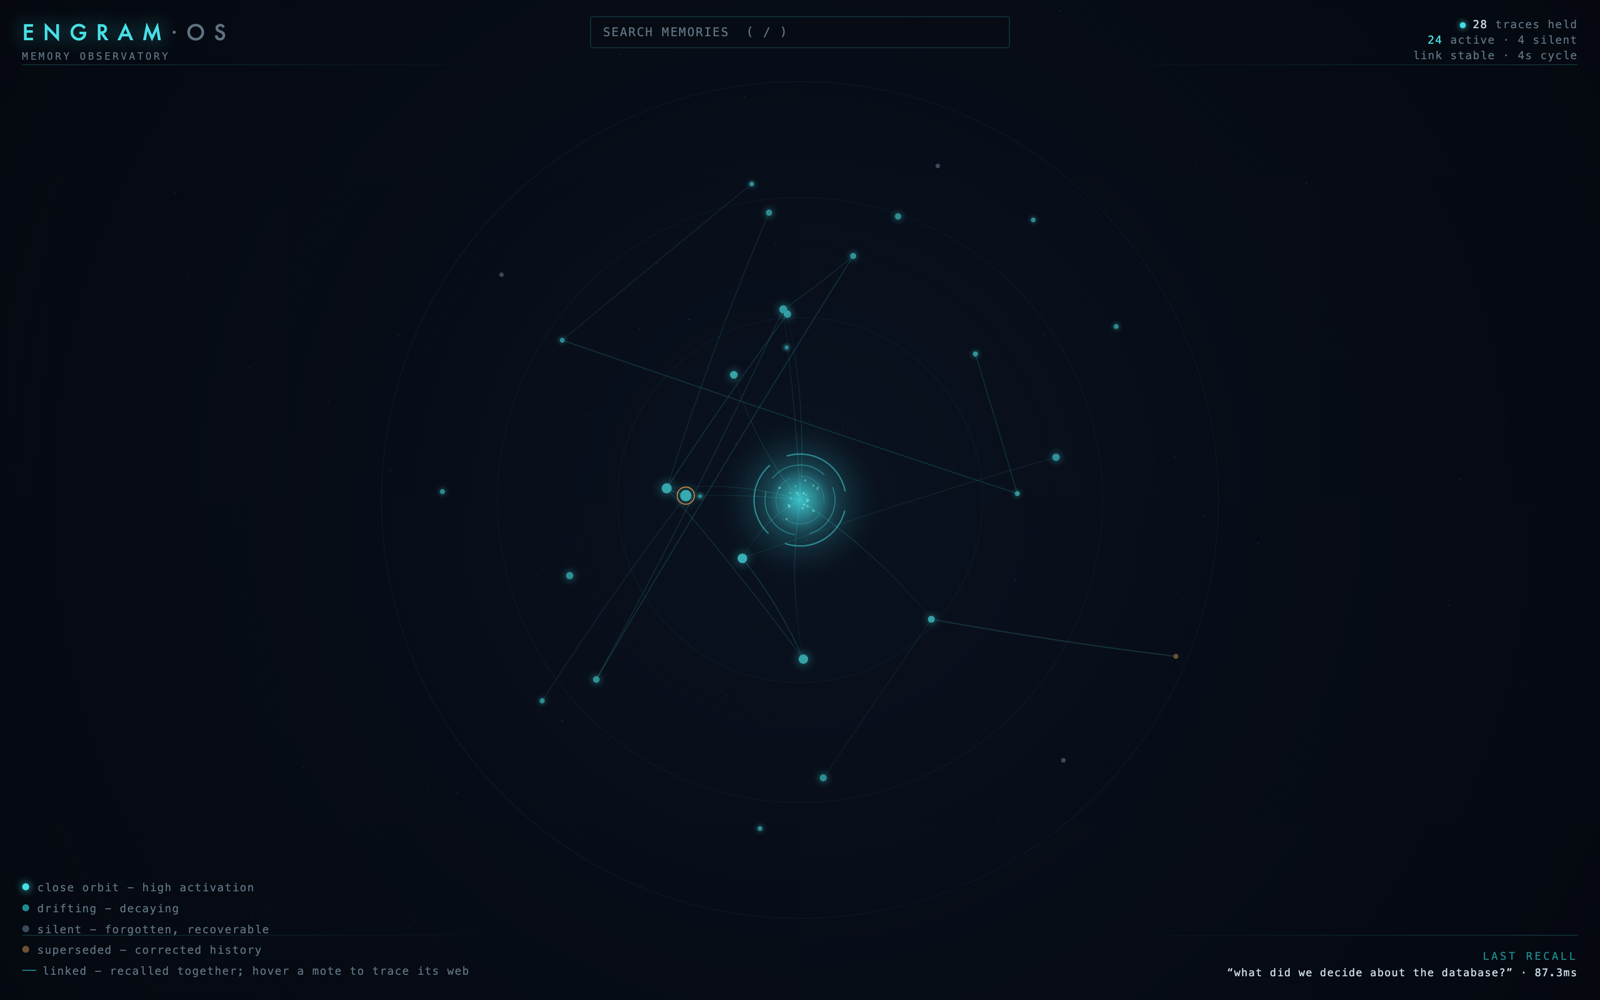
A live store (demo data). Closer orbits are hotter memories; filaments are the hebbian graph between memories recalled together; the ember-ringed mote is pinned; the faint outer motes are silent and superseded history.
One line per client
# stock Ollama CLI
export OLLAMA_HOST=127.0.0.1:11435

# OpenClaw (keeps its native-API mode)
{ "providers": { "engram": { "baseUrl": "http://127.0.0.1:11435", "api": "ollama" } } }

# Hermes Agent, or any OpenAI-compatible client
base_url = "http://127.0.0.1:11435/v1"

# Anthropic-protocol cloud (e.g. MiniMax) with local memory
ENGRAM_ANTHROPIC_UPSTREAM=https://api.minimax.io engram up
# then point the client at http://127.0.0.1:11435/anthropic

# OpenAI-protocol cloud (OpenRouter, DeepSeek, ...) with local memory
ENGRAM_OPENAI_UPSTREAM=https://openrouter.ai/api engram up
# then point the client at http://127.0.0.1:11435/v1
Step-by-step recipes: the Hermes Agent and OpenClaw integration guide. Requires Ollama with qwen3:1.7b + qwen3-embedding:0.6b (~2 GB total) for background summarization and retrieval - even when your chat model is in the cloud.